Self-service delivery on an existing Kubernetes platform
A proposed workflow for reducing deployment handoffs, with explicit ownership, versioned templates, and a measured pilot.
Assumptions and constraint
Assume several product teams already deploy to shared Kubernetes clusters, store deployment configuration in Git, and need isolated environments. The operations team can maintain a GitOps controller and shared release checks. The question is how to reduce routine handoffs within that setup.
Environment requests currently wait for an operations engineer. Teams copy deployment configuration between repositories, while service ownership and required checks are inconsistent. A faster interface alone would leave those underlying problems intact.
Decision: automate one workflow before building a portal
I would start with a versioned service template and a shared delivery workflow. A team would supply its configuration through Git; CI would test the change, build the artifact, and attach the required release evidence. Policy checks would validate that evidence before GitOps reconciles the approved deployment configuration.
The template would include health checks, resource requests, and ownership metadata. Build provenance and a software bill of materials would follow the artifact digest through promotion, rather than becoming detached reports.
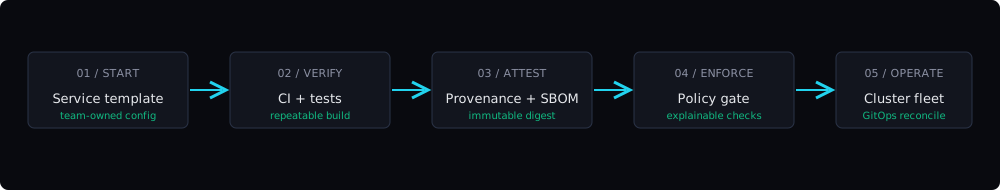
Open the full-size delivery diagram.
A portal could later improve discovery and guide requests, but I would defer it until the underlying workflow is usable and maintained. Otherwise, it risks becoming another front end to an operations queue. Letting each team maintain an independent pipeline would avoid a shared dependency, but would also duplicate maintenance and make controls harder to apply consistently.
Trade-off: shared defaults need an owner
Templates reduce repeated setup but can create configuration drift after teams copy them. I would version the shared components, document supported customisations, and provide an upgrade path. The platform team would own those components and their compatibility; product teams would own application configuration, service readiness, and on-call response.
GitOps makes desired state reviewable and reconciliation visible. It also introduces a controller that needs monitoring, upgrades, and a recovery procedure. Those operating costs belong in the design decision.
Failure and recovery
A rejected release should identify the failed check and the responsible owner. The pilot would exercise missing artifact evidence, invalid configuration, and an unavailable deployment controller. Recovery would include restoring a previously approved configuration and confirming service health; reverting manifests alone would not establish that application data remains compatible.
Evaluation plan
I would pilot one representative service and measure the existing workflow first: provisioning wait, manual handoffs, failed deployments, recovery time, and support requests. Then I would compare equivalent tasks through the proposed workflow, including setup and maintenance effort.
Team feedback would test whether the new path is understandable and usable without routine intervention. Adoption would be useful context, but the decision to expand would depend on reduced friction without increased operational risk.